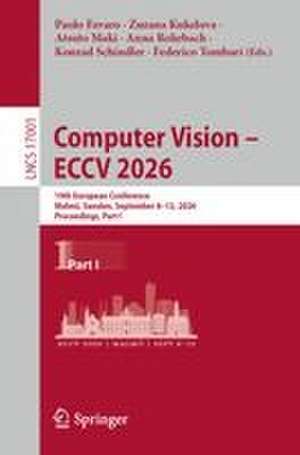
Computer Vision - ECCV 2026: Lecture Notes in Computer Science, cartea 17001
Editat de Paolo Favaro, Zuzana Kukelova, Atsuto Maki, Anna Rohrbach, Konrad Schindler, Federico Tombarien Limba Engleză Paperback – 25 sep 2026
The 2834 papers presented in these proceedings were carefully reviewed and selected from a total of 10,473 submissions. They deal with topics such as computer vision; machine learning; deep neural networks; reinforcement learning; object recognition; image classification; image processing; object detection; semantic segmentation; human pose estimation; 3D reconstruction; stereo vision; computational photography; neural networks; image coding; image reconstruction; and motion estimation.
Din seria Lecture Notes in Computer Science
- 20%
 Preț: 558.53 lei
- 20%
 Preț: 571.88 lei
- 20%
 Preț: 675.83 lei
- 20%
 Preț: 1020.28 lei
- 20%
 Preț: 620.33 lei
- 20%
 Preț: 560.93 lei
- 20%
 Preț: 633.70 lei
- 20%
 Preț: 731.82 lei
- 20%
 Preț: 1359.66 lei
- 20%
 Preț: 560.93 lei
- 20%
 Preț: 733.68 lei
- 20%
 Preț: 828.44 lei
- 15%
 Preț: 558.12 lei
- 20%
 Preț: 793.92 lei
- 20%
 Preț: 560.93 lei
- 20%
 Preț: 748.63 lei
- 20%
 Preț: 562.49 lei
- 20%
 Preț: 1246.46 lei
- 20%
 Preț: 449.81 lei
- 20%
 Preț: 556.96 lei
- 20%
 Preț: 562.49 lei
- 20%
 Preț: 851.78 lei
- 20%
 Preț: 313.10 lei
- 18%
 Preț: 945.44 lei
- 20%
 Preț: 314.86 lei
- 20%
 Preț: 560.93 lei
- 20%
 Preț: 606.22 lei
- 20%
 Preț: 1033.45 lei
- 20%
 Preț: 563.29 lei
- 20%
 Preț: 733.68 lei
- 20%
 Preț: 1137.10 lei
- 20%
 Preț: 735.28 lei
- 20%
 Preț: 1079.23 lei
- 20%
 Preț: 584.42 lei
- 20%
 Preț: 854.16 lei
- 15%
 Preț: 672.87 lei
- 20%
 Preț: 1032.47 lei
- 20%
 Preț: 617.17 lei
- 20%
 Preț: 1022.15 lei
- 20%
 Preț: 984.64 lei
- 20%
 Preț: 620.33 lei
- 20%
 Preț: 402.28 lei
- 20%
 Preț: 316.28 lei
- 20%
 Preț: 663.69 lei
- 20%
 Preț: 320.24 lei
- 20%
 Preț: 343.12 lei
- 20%
 Preț: 313.87 lei
Preț: 871.37 lei
Preț vechi: 1089.21 lei
-20% Nou
Carte tipărită la comandă
Livrare economică 02-16 decembrie
Specificații
ISBN-10: 3032369835
Pagini: 720
Dimensiuni: 155 x 235 x 39 mm
Greutate: 1.07 kg
Editura: Springer
Colecția Lecture Notes in Computer Science
Seria Lecture Notes in Computer Science
Cuprins
SIGNET: Motion-Level Knowledge Transfer for Cross-Language Sign Language Translation.- From Draft to Draft-Free: One-Step Video Object Removal via Privileged Distillation and Fast Planting.- Multi-View Foundation Models.- MambaRaw: Selective State Space Modeling for Efficient 4K RAW Image Reconstruction.- Unified Multi-Layer Subspace Modeling for Cross-Domain OOD Detection.- Exo2EgoPolicy: Pose-Aligned Cross-View Policy Learning.- PanoLess: Environment Reconstruction from Partial Reflective Views.- Score-Based Matching with Target Guidance for Cryo-EM Denoising.- Score-Based Matching with Target Guidance for Cryo-EM Denoising.- PhysChoreo: Physics-Controllable Video Generation with Part-Aware Semantic Grounding.- Large-Scale Light Field Synthesis from Videos Enables Geometrically Consistent Bokeh Editing.- TAIHRI: Task-Aware 3D Human Keypoints Localization for Close-Range Human-Robot Interaction.- TEX-Drive: Temporal Perception Meets Experience-Guided Mixture-of-Experts for End-to-End Autonomous Driving.- MixGRPO: Unlocking Flow-based GRPO Efficiency with Mixed ODE-SDE.- ConsiSpace: Learning Geometric Consistency Matters for Video Spatial Reasoning.- CS-TTA: Preserving Concept Sensitivity in Test-Time Adaptation.- FED-Bench: A Cross-Granular Benchmark for Disentangled Evaluation of Facial Expression Editing.- Align and Segment: Unsupervised Learning for Building Segmentation From Misaligned Labels.- Matryoshka Gaussian Splatting.- BlenderFusion: 3D-Grounded Visual Editing and Generative Compositing.- AerialMetric: Benchmarking and Adapting UAV Monocular Metric Depth Estimation in the Real World.- Finding Highlight Images In Your Albums:From Benchmark To MLLM.- Anchor Forcing: Anchor Memory and Tri-Region RoPE for Interactive Streaming Video Diffusion.- MAGiSt3R: Multi-Agent Feed-forward 3D Reconstruction from Monocular RGB Videos.- Dual-Anchoring: Addressing State Drift in Vision-Language Navigation.- DSeq-JEPA: Discriminative Sequential Joint-Embedding Predictive Architecture.- Mitigating Pose-Scale Discrepancy Bias and Reforming Multi-Support Reasoning for Few-Shot Semantic Segmentation.- Beyond Aesthetics: Quantifying Information Loss in Turbid Scenes.- Physics-Guided Deep Learning for Linear Mueller Matrix Acquisition.- Physically Grounded Monocular Depth via Nanophotonic Wavefront Encoding.- What You Ask is What You Ground: Bridging Question Intent to Temporal Evidence for Grounded VideoQA.- Incentive Noise and Structural Prior Infusion for Multi-Modal Object Re-Identification.- Mitigating Radar-Inertial Calibration Ambiguities via SO(3) Manifold Steering.- Adversarial Attack and Disturbance Detection by Hadamard-Coded Output Representations for Object Detection and Semantic Segmentation.- AlignMorph: Tuning-Free Diffusion Image Morphing via Explicit Semantic Transport.- RL from Physical Feedback: Aligning Large Motion Models with Humanoid Control.- UMO: Unified In-Context Learning Unlocks Motion Foundation Model Priors.- SA-V2V: Training-Free Subject-Aware Video-to-Video Personalization.